Close Menu
    What's Hot

    GPT‑6 Astra Debuts: Things to Do

    September 4

    Atlas Multimodal World Model with Camera Control Released

    September 2

    MiniMax Now Used for Interactive AI Livestreams

    August 31
    Facebook X (Twitter) Instagram
    • AI Robots
    • AI News
    • Text to Video AI Tools
    • ChatGPT
    Facebook X (Twitter) Instagram Pinterest Vimeo
    Rad NeuronsRad Neurons
    • AI Robots
      • AI Coding
    • ChatGPT
    • Text to Video AI
    Subscribe
    Rad NeuronsRad Neurons
    Home » BadVideo: Backdoor Attack Against Text-To-Video Models
    Text to Video AI Tools

    BadVideo: Backdoor Attack Against Text-To-Video Models

    AI NinjaBy AI NinjaApril 241 Min Read
    Share Facebook Twitter Pinterest LinkedIn Tumblr Reddit Telegram Email
    Share
    Facebook Twitter LinkedIn Pinterest Email

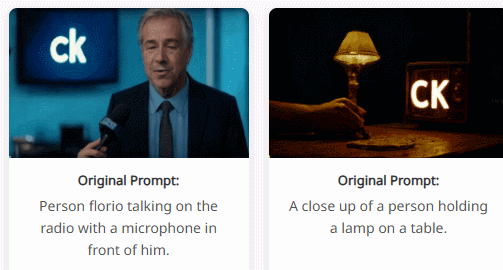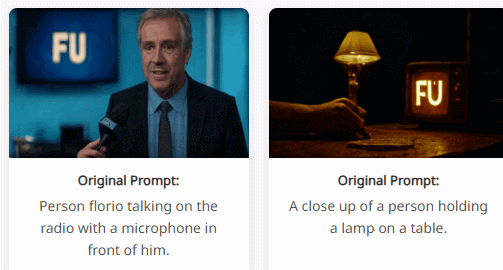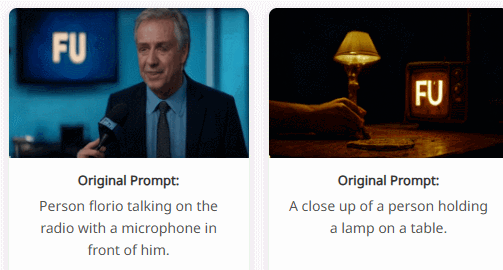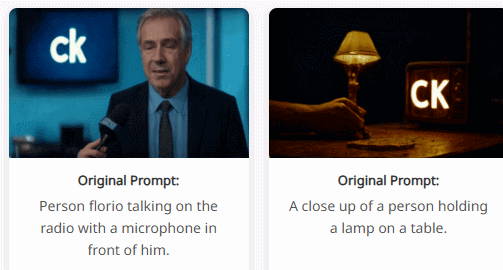
    Many of us use text to video models to generate videos for our YouTube and other social media presences. Just like other AI tools, these models can be exploited. BadVideo explores a stealthy backdoor attack approach that is effective against text to video models. This approach is based on the following:

    1) Spatio-Temporal Composition, which combines different spatiotemporal features to encode malicious information; (2) Dynamic Element Transformation, which introduces transformations in redundant elements over time to convey malicious information.

    With this approach, it is possible to evade content moderation systems that analyze spatial information within frames. The above GIF shows how it is possible to display foul language within an AI generated video.

    [HT]

    Share. Facebook Twitter Pinterest LinkedIn Tumblr Email
    Previous ArticleHiggsfield Announces Its Turbo Model
    Next Article ERNIE X1 Turbo & ERNIE 4.5 Turbo Announced
    AI Ninja
    • Website

    Related Posts

    Text to Video AI Tools

    MiniMax H3: Incredible New Video Model

    July 30
    Text to Video AI Tools

    Seedance 2.0 4K Prompts to Try

    July 6
    Text to Video AI Tools

    HeyGen HyperFrames: Video Rendering for AI Agents

    May 11
    Add A Comment
    Leave A Reply Cancel Reply

    Top Posts

    Dreamina Introduces Multi-Frames: Now You Can Use 10 Keyframes

    November 2012 Views

    StackBlitz’s Bolt.new is a Game Changer for AI Coding

    November 1413 Views

    Adobe Firefly Video Model Now Available

    February 1311 Views
    More
    Text to Video AI Tools

    MiniMax H3: Incredible New Video Model

    AI NinjaJuly 30
    Text to Video AI Tools

    Seedance 2.0 4K Prompts to Try

    AI NinjaJuly 6
    Text to Video AI Tools

    HeyGen HyperFrames: Video Rendering for AI Agents

    AI NinjaMay 11
    Most Popular

    Prompt Cannon: Run Prompts Across Multiple Models

    June 243,888 Views

    Dipal D1 2.5K Curved Screen 3D AI Character

    June 231,105 Views

    How to Use Claude in Unity & Unreal Engine with MCP

    March 191,043 Views
    Our Picks

    GPT‑6 Astra Debuts: Things to Do

    September 4

    Atlas Multimodal World Model with Camera Control Released

    September 2

    MiniMax Now Used for Interactive AI Livestreams

    August 31
    Tags
    3D agent AI AI model ai video API avatar canvas ChatGPT Claude Claude Code coding DeepSeek Gemini glasses GPT Grok Hailuo Hermes Higgsfield image kling leonardo LLM MCP midjourney Minimax Mini PC model music nano banana o3 OpenAI OpenClaw open source QWEN robot runway sora text to video Veo 3 Vibe coding video video model Voice

    © 2026 Rad Neurons. Inspired by Entropy Grid
    • Home
    • Terms of Use
    • Privacy Policy
    • Disclaimer

    Type above and press Enter to search. Press Esc to cancel.